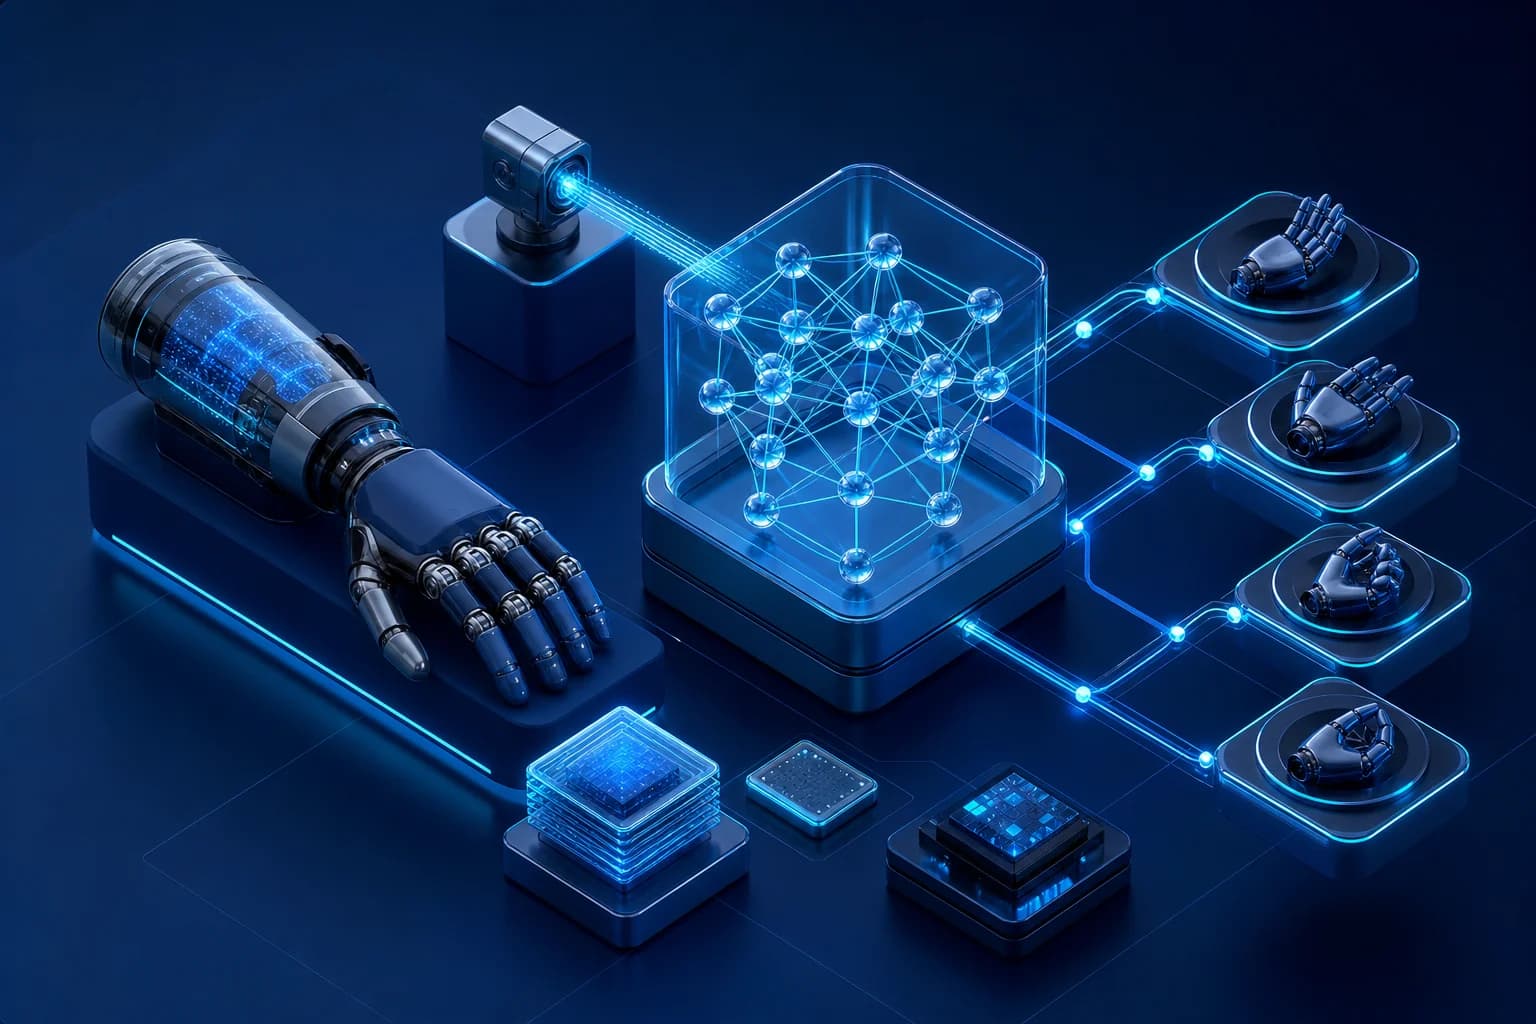
Toronto-based startup smartARM is advancing the field of prosthetic robotics by integrating Meta’s DINOv2 vision model into a bionic arm prototype, effectively automating grip selection for users with limb differences. The system utilizes a palm-embedded camera to process visual data, allowing the device to identify and interact with objects without the manual pattern switching required by traditional prosthetic interfaces.
The core of the smartARM architecture relies on DINOv2, a self-supervised vision transformer, to facilitate object recognition from minimal reference samples. By utilizing this model, the system performs direct visual feature extraction, which enables the prosthetic to adapt to new objects in near real-time. This approach replaces the conventional, labor-intensive programming cycles that previously necessitated weeks of training for each new object class.
The DINOv2 model architecture allows the prosthetic to map visual features to specific motor outputs without requiring extensive labeled datasets for every potential object. By processing these features through a lightweight inference engine, the arm achieves the necessary latency to perform tasks in dynamic, real-world environments. This capability ensures that the prosthetic can distinguish between objects with similar geometries but different functional requirements, such as a glass and a spoon.
The integration of Meta AI glasses provides an additional data stream, utilizing the Meta Wearables Device Access Toolkit to enhance the prosthetic’s egocentric context. By capturing environmental data from the user’s perspective, the system gains a broader understanding of the immediate operational space. This multimodal input allows the arm to correlate visual cues with the user’s intended interaction, significantly reducing the cognitive load associated with manual prosthetic control.
Data scientists at the firm have implemented a workflow where users can register new objects via a mobile application, which then updates the recognition model for the broader community. This crowdsourced data collection method allows for the rapid expansion of the prosthetic’s object library. The system effectively treats the prosthetic as an edge-computing device, performing complex inference locally to ensure low-latency performance during daily tasks.
The technical implementation relies on the ability of the vision model to generalize across varying lighting conditions and object orientations. By training the model on diverse visual inputs, the developers have ensured that the prosthetic maintains high performance even when the camera’s field of view is partially obstructed. This adaptability is critical for maintaining the reliability of the grip-selection software in unpredictable domestic settings.
Hamayal Choudhry, founder and CEO of smartARM, emphasizes that the primary engineering challenge lies in the intuitiveness of the human-machine interface rather than the mechanical dexterity of the hand itself. The development team focuses on minimizing the operational complexity for the user, prioritizing uninterrupted interaction over the manual selection of grip patterns. This shift in focus represents a move toward autonomous prosthetic adjustment based on environmental perception.
Shaquem Griffin, a long-time user of the technology, notes that the scalability of this approach is essential for the future of consumer-grade prosthetics. The system’s ability to function effectively upon initial deployment without extensive user training highlights the efficacy of the vision-first control architecture. This capability underscores the potential for computer vision models to solve long-standing usability issues in assistive robotics.
The technical architecture demonstrates how vision-first models can be applied to physical hardware to solve specific, high-stakes usability problems. By moving away from rigid, pre-programmed grip sequences, the system allows for a more fluid interaction between the user and their environment. This development marks a shift toward more adaptive, AI-driven assistive technologies that rely on real-time environmental inference.
Future iterations of the smartARM platform will likely focus on refining the latency of the vision-processing pipeline and expanding the reliability of the object recognition model. Researchers are monitoring how the integration of egocentric data from wearable devices influences the accuracy of grip selection in complex, cluttered environments. The ongoing refinement of these models will determine the long-term viability of vision-first control systems in clinical and daily-living applications.