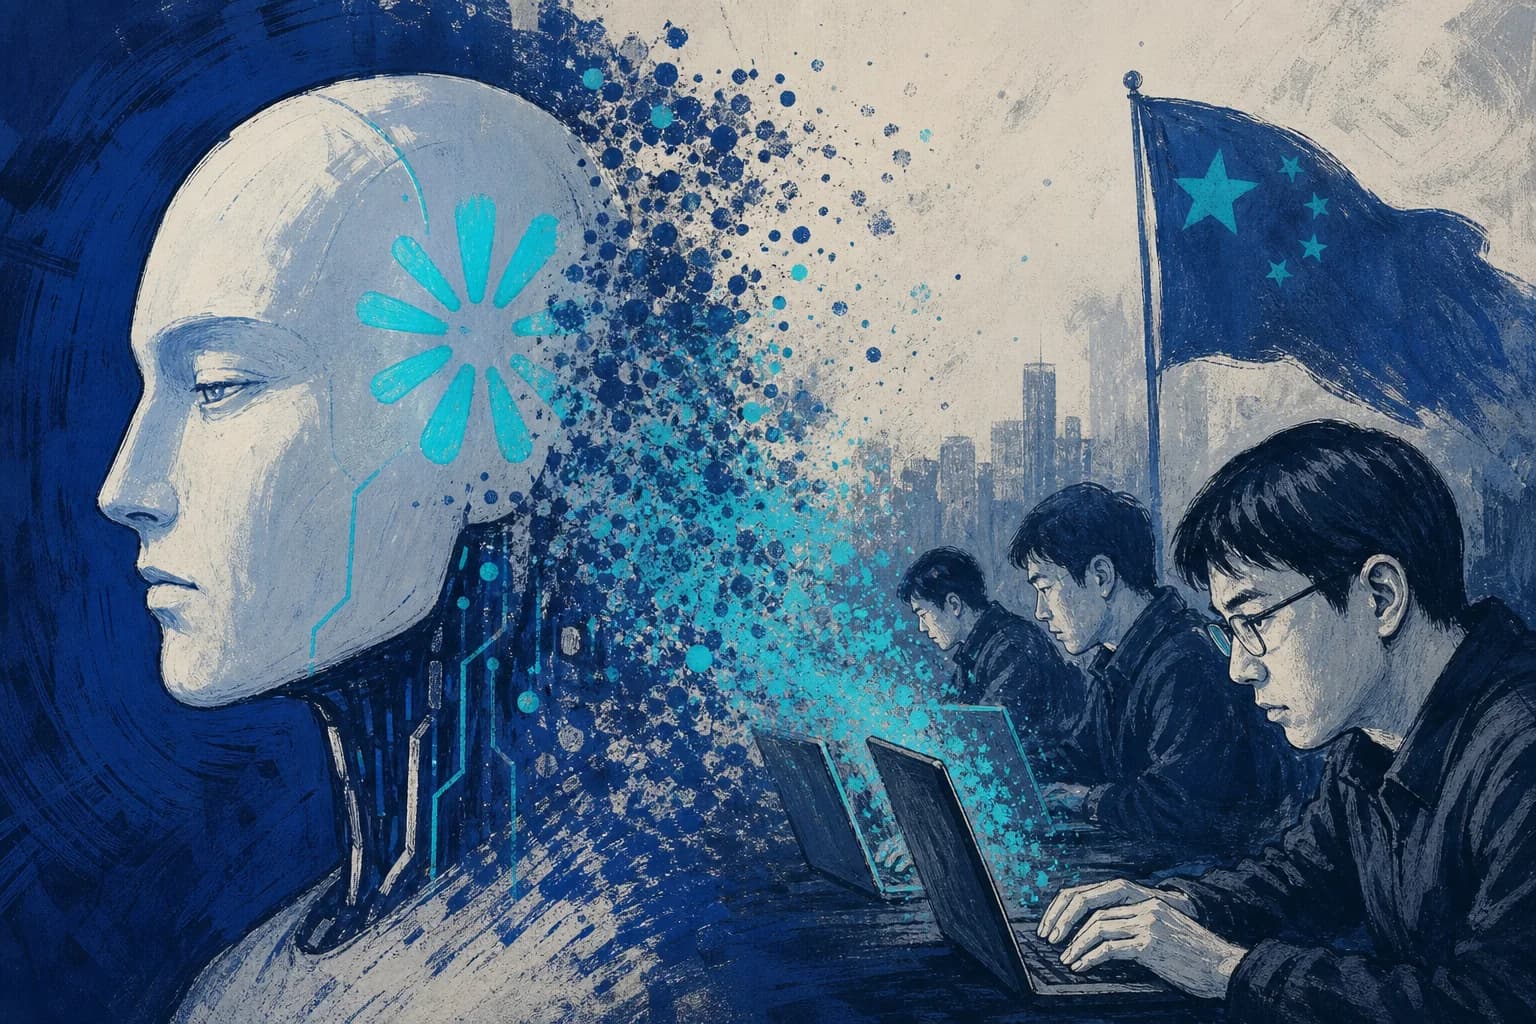
Anthropic has formally accused several Chinese artificial intelligence developers of orchestrating a large-scale data extraction campaign targeting its Claude model architecture between May and July 2026. The company reports that Alibaba, Moonshot AI, DeepSeek, Zhipu, and Xiaomi collectively executed nearly 190 million distillation attacks to harvest reasoning outputs for their own model training pipelines.
Model distillation involves leveraging the high-fidelity outputs of a frontier model to fine-tune a smaller, less computationally expensive system. Anthropic asserts that the scale of these operations, which utilized thousands of fraudulent accounts, represents an unauthorized and abusive application of its proprietary reasoning capabilities. The company identified Alibaba as the primary actor, alleging that over 3,500 accounts generated 151 million exchanges designed to capture Claude’s internal reasoning processes for the Qwen model series.
The scope of this activity appears to have escalated significantly since June, when Sarah Heck, head of policy at Anthropic, first alerted United States lawmakers to 28.8 million illicit exchanges. Subsequent data analysis revealed that Moonshot AI rerouted 23 million requests through Claude, while DeepSeek allegedly funneled 12.1 million queries over a concentrated 14-day period in July. These mechanisms allowed the firms to bypass the computational costs of training their own models from scratch by offloading complex reasoning tasks to Anthropic’s infrastructure.
Technical analysis by Anthropic indicates that these rerouted requests often contained sensitive information, including data linked to Russian and Chinese military activities. One documented instance involved the submission of CCTV footage from a user of the Kimi platform, which is affiliated with the People’s Liberation Army. Another case involved a Russian military contractor uploading proprietary database information into the system under the guise of interacting with a local model.
Distinguishing between legitimate user queries and distillation-focused traffic presents a significant technical challenge for Anthropic’s engineering teams. The attackers employ sophisticated obfuscation techniques, including randomized request patterns and varied prompt structures, to mimic human interaction and evade standard rate-limiting heuristics. Because the system is designed to be highly responsive to complex reasoning tasks, identifying the specific intent behind a query requires deep analysis of the semantic structure of the output rather than just the input volume.
Xiaomi allegedly employed a different methodology, recording user conversations with its MiMo models and subsequently feeding those transcripts into Claude to generate synthetic training data. Anthropic also identified Z.ai as a participant, noting that the firm utilized similar techniques to enhance its Ox Alpha model. This pattern of behavior suggests a systematic effort to capture the latent knowledge embedded within frontier models to accelerate the development of domestic Chinese alternatives.
The incident underscores a significant vulnerability in the current paradigm of providing open-access interfaces for highly capable large language models. While these interfaces drive commercial adoption, they simultaneously expose the underlying reasoning weights to competitors seeking to achieve parity without equivalent investment in research and development. Controlling access to model outputs has now emerged as a critical component of the race for model parity among developers.
Anthropic has responded by implementing more rigorous defensive measures, including the introduction of advanced heuristics to detect and block automated, high-volume traffic. The company is also restricting the granularity of reasoning transcripts provided to users to limit the utility of the output for distillation purposes. Furthermore, Anthropic will mandate identity verification for users operating from jurisdictions where the service is not officially available, such as China, Russia, and Iran.
These developments highlight how the provenance of training datasets directly dictates the integrity and performance of modern neural networks. Researchers note that the reliance on distillation from frontier models complicates the ability of developers to maintain a competitive advantage through architectural innovation alone. Future stability in the sector may depend on the development of more robust authentication protocols and the implementation of stricter usage policies regarding the automated ingestion of model outputs.