OpenAI has introduced Astra, a multimodal system engineered to process live video inputs alongside natural language interaction. This architecture transitions from monolithic processing to a modular framework, as detailed in recent reports from The New York Times regarding the company’s research trajectory.
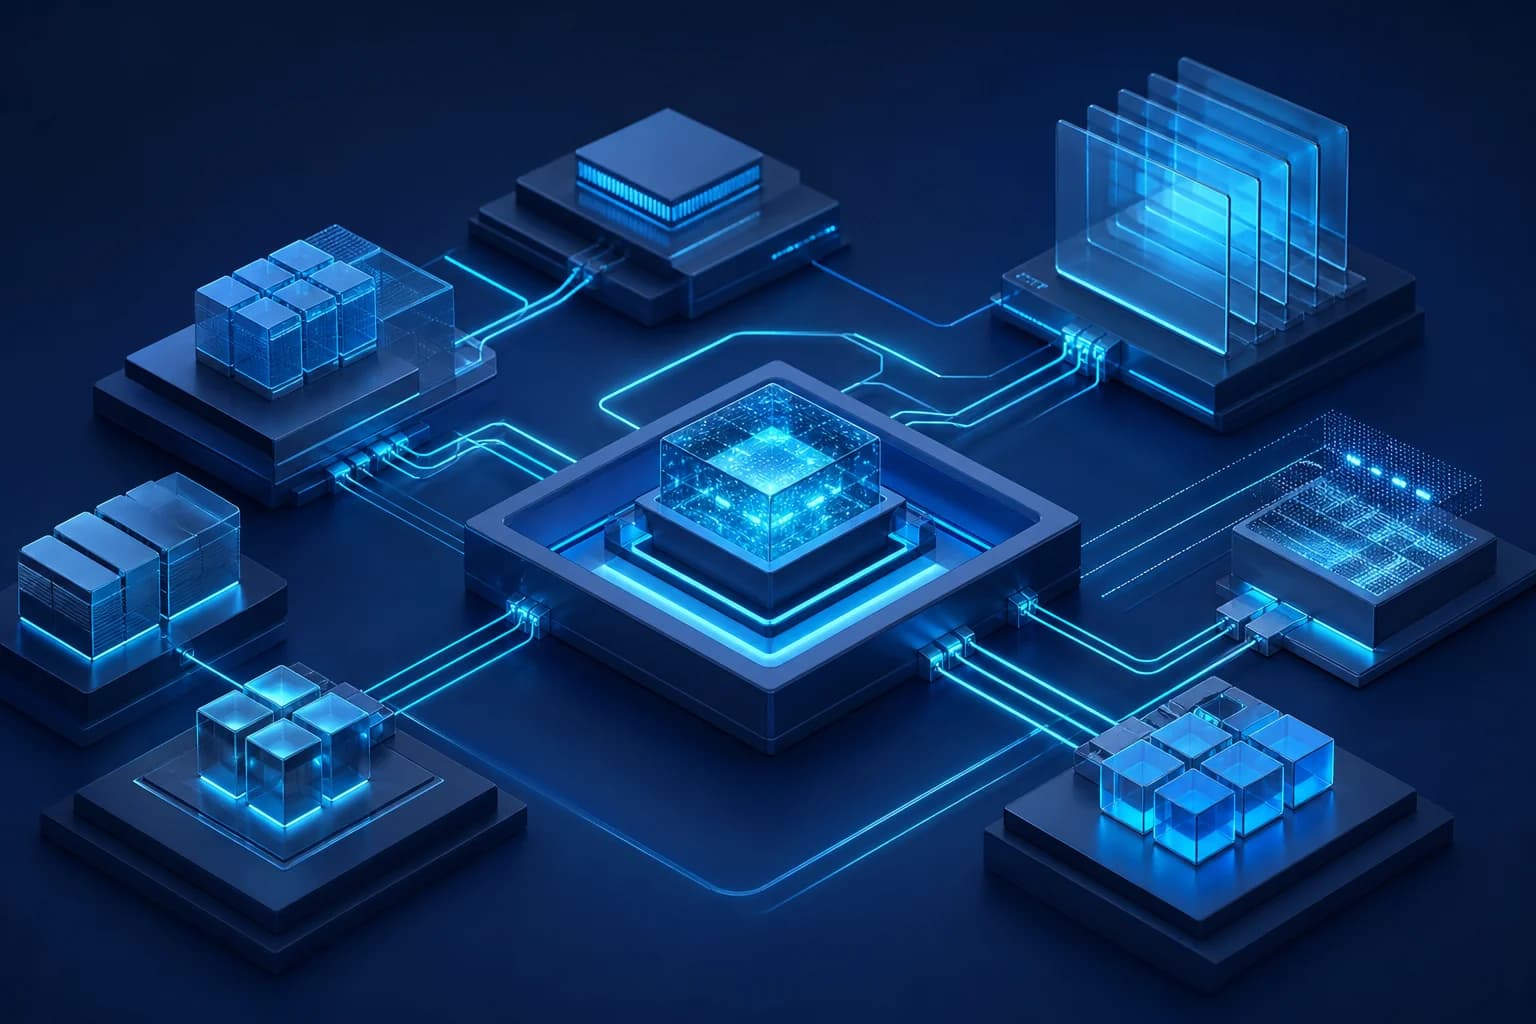
The architecture relies on a modular design that separates visual feature extraction from language generation. By utilizing distinct neural pathways, the system enables safety filters to intercept visual data before it reaches the core reasoning components. This decoupling allows for granular control over input processing without necessitating a complete re-training of the language model.
Engineers addressed the challenges of continuous data streams by implementing a limited context window for visual information. Unlike systems that utilize persistent storage for environmental mapping, Astra discards visual tokens upon the termination of a session. This design choice minimizes privacy risks while maintaining sufficient coherence for short-term task completion.
The training methodology involved specialized datasets designed to mitigate the risks of harmful output generation. Researchers curated these sets to exclude problematic visual scenarios while preserving the model’s performance on standard object recognition tasks. This approach was supplemented by custom evaluation environments that simulated dynamic lighting and occluded objects, which static benchmarks failed to capture.
Safety interventions occur in parallel with inference to manage latency requirements. By performing safety evaluations concurrently with processing tasks, the system avoids the performance degradation typical of sequential filtering. This parallelization requires significant computational overhead, currently limiting deployment to specific hardware configurations.
The system utilizes a multi-stage pipeline where visual tokens are passed through convolutional layers before being projected into the latent space of the transformer. By monitoring the activation patterns within these specific layers, engineers can identify anomalous inputs that deviate from the training distribution. This granular monitoring ensures that the model maintains high accuracy on complex diagnostic tasks while rejecting inputs that fall outside of defined safety parameters.
External red teaming exercises identified critical vulnerabilities in the initial model iterations. Independent experts attempted to bypass safety guardrails through adversarial prompting and unconventional camera movements. These findings prompted iterative adjustments to the filtering logic, ensuring that the system maintains consistency when interpreting ambiguous visual inputs.
The integration of visual and linguistic modalities necessitates a delicate balance between responsiveness and safety. When filters activate prematurely, the system risks flagging benign objects that share visual characteristics with restricted items. Conversely, delayed activation allows potentially harmful content to influence the internal reasoning state of the model.
The development of Astra highlights the technical complexity of building systems that operate on unstructured, real-time visual data. The reliance on modular pathways suggests a move toward more interpretable and controllable AI architectures. Future iterations will likely focus on refining these filters to improve accuracy while reducing the computational cost of parallel processing.
Researchers continue to monitor the system’s performance through anonymized usage logs. These data points provide insights into the frequency of safety filter activations and the types of queries users submit. Such empirical evidence will inform subsequent refinements to the model’s guardrails and its underlying neural architecture.
The deployment of Astra serves as a case study in the trade-offs between system speed and safety. By prioritizing consistent refusal behaviors over raw processing breadth, the model demonstrates a conservative approach to multimodal deployment. The engineering team focused on optimizing the cross-attention mechanisms to ensure that visual inputs do not degrade the semantic quality of the generated text, even under high-load scenarios.
The technical team at OpenAI emphasized that the system’s ability to handle foreign language translation and appliance repair diagnostics relies on high-fidelity visual tokenization. By maintaining a strict separation between the visual encoder and the language decoder, the system prevents the leakage of sensitive visual data into the generative output. This structural integrity remains the primary defense against potential privacy violations during active user sessions.