Ceva, Inc. announced on October 28, 2026, the launch of its next-generation NeuPro neural processing unit (NPU) portfolio, marking a strategic shift toward AI infrastructure alongside its established edge computing offerings, according to the official company press release. The new architecture delivers a two-fold increase in AI throughput per square millimeter and a 50% improvement in power efficiency compared to the company’s initial NPU generation.
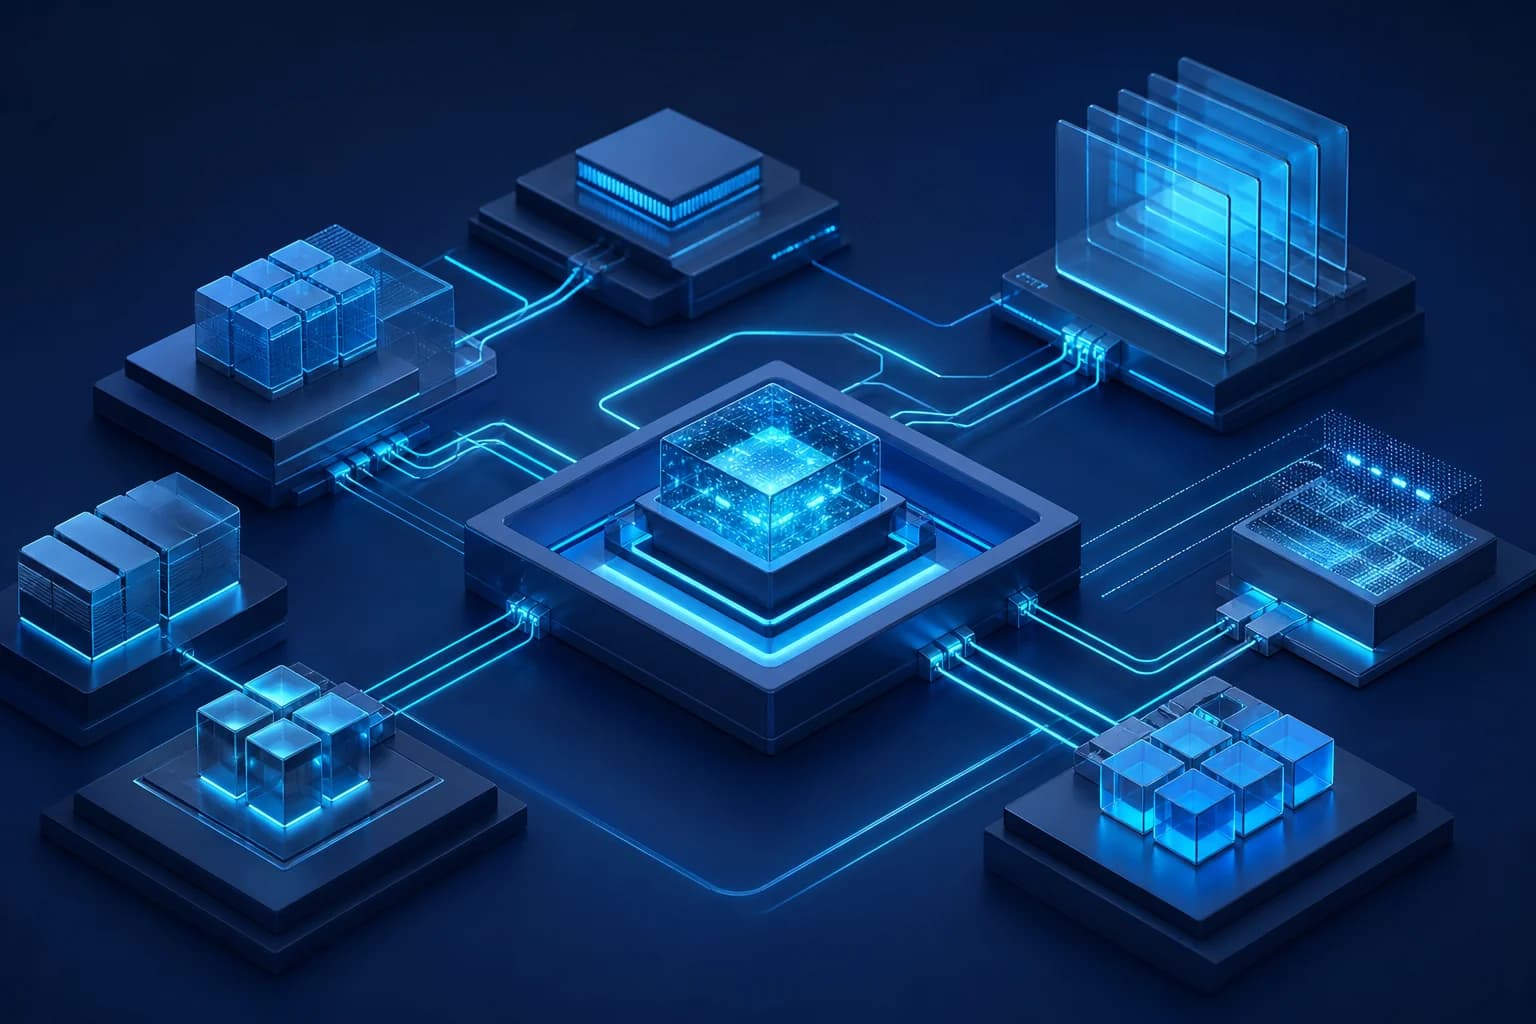
The portfolio utilizes a common core architecture and a unified software development kit (SDK) designed to support diverse workloads ranging from always-on sensor perception to complex data center inference. By standardizing the development environment, semiconductor designers can integrate multiple NPU variants within a single system-on-chip (SoC) while maintaining software compatibility across different performance tiers.
Yaron Galitzky, Executive Vice President of the AI Division at Ceva, stated that the architecture was refined based on performance data from over 15 initial licensees. The design focuses on balancing compute, memory bandwidth, and power consumption to accommodate the evolving requirements of multimodal and agentic AI models.
The technical specifications of the new NeuPro architecture include support for advanced AI numerics, specifically FP4 and FP8 precision, to optimize inference efficiency. These capabilities are intended to reduce memory footprint and data movement, which are critical bottlenecks in modern transformer-based architectures.
Memory management features have been significantly enhanced to support longer context windows and memory-intensive operations. The inclusion of dynamic shapes and paged KV cache mechanisms allows the hardware to handle the complex memory access patterns typical of large language models and mixture-of-experts networks.
The portfolio is segmented into four distinct engines: the NeuPro Nano for constrained sensing, the NeuPro Prime for mainstream CNN and transformer tasks, the NeuPro Max for advanced edge AI, and the NeuPro Ultra for AI infrastructure. This modular approach enables silicon developers to scale their hardware designs while leveraging a consistent toolchain and integration workflow.
NeuPro Ultra specifically addresses the growing demand for high-performance cloud inference, supporting multi-core processing and multi-user operation. By integrating neural processing directly into memory and connectivity subsystems, the architecture aims to minimize data transfer overheads that frequently limit throughput in large-scale AI deployments.
The NeuPro Ultra engine provides a specialized solution for memory-bound workloads by offloading data-intensive operations from the primary processor. This hardware-level optimization reduces the latency associated with fetching weights and activations from external DRAM, which is a common performance ceiling for large language model inference. By integrating neural processing closer to the data source, the architecture ensures that compute resources are not left idle while waiting for memory access, thereby maximizing the effective utilization of the multiply-accumulate units.
Amir Panush, Chief Executive Officer of Ceva, noted that the expansion into AI infrastructure represents a broader effort to embed neural processing capabilities into a wider array of semiconductor products. This approach allows developers to utilize established IP foundations rather than building custom NPU platforms from the ground up.
The industry faces a persistent challenge in optimizing inference performance as model complexity increases and memory bandwidth becomes a primary constraint. By providing architectural flexibility and native support for pre-quantized models, the new portfolio seeks to streamline the deployment lifecycle for semiconductor companies.
The shift toward hybrid AI systems necessitates a more granular approach to compute distribution, where perception tasks occur at the sensor level while reasoning is offloaded to the cloud. Ceva’s strategy addresses the power-performance trade-offs inherent in these distributed systems by offering engines sized for specific points in the data pipeline.
Future deployments will likely focus on the integration of these NPUs into specialized silicon for data centers, where memory-bound workloads demand increasingly efficient compute-to-memory ratios. Ceva plans to provide further technical details regarding its Physical AI strategy during upcoming symposiums in Hsinchu and Shanghai in November 2026.