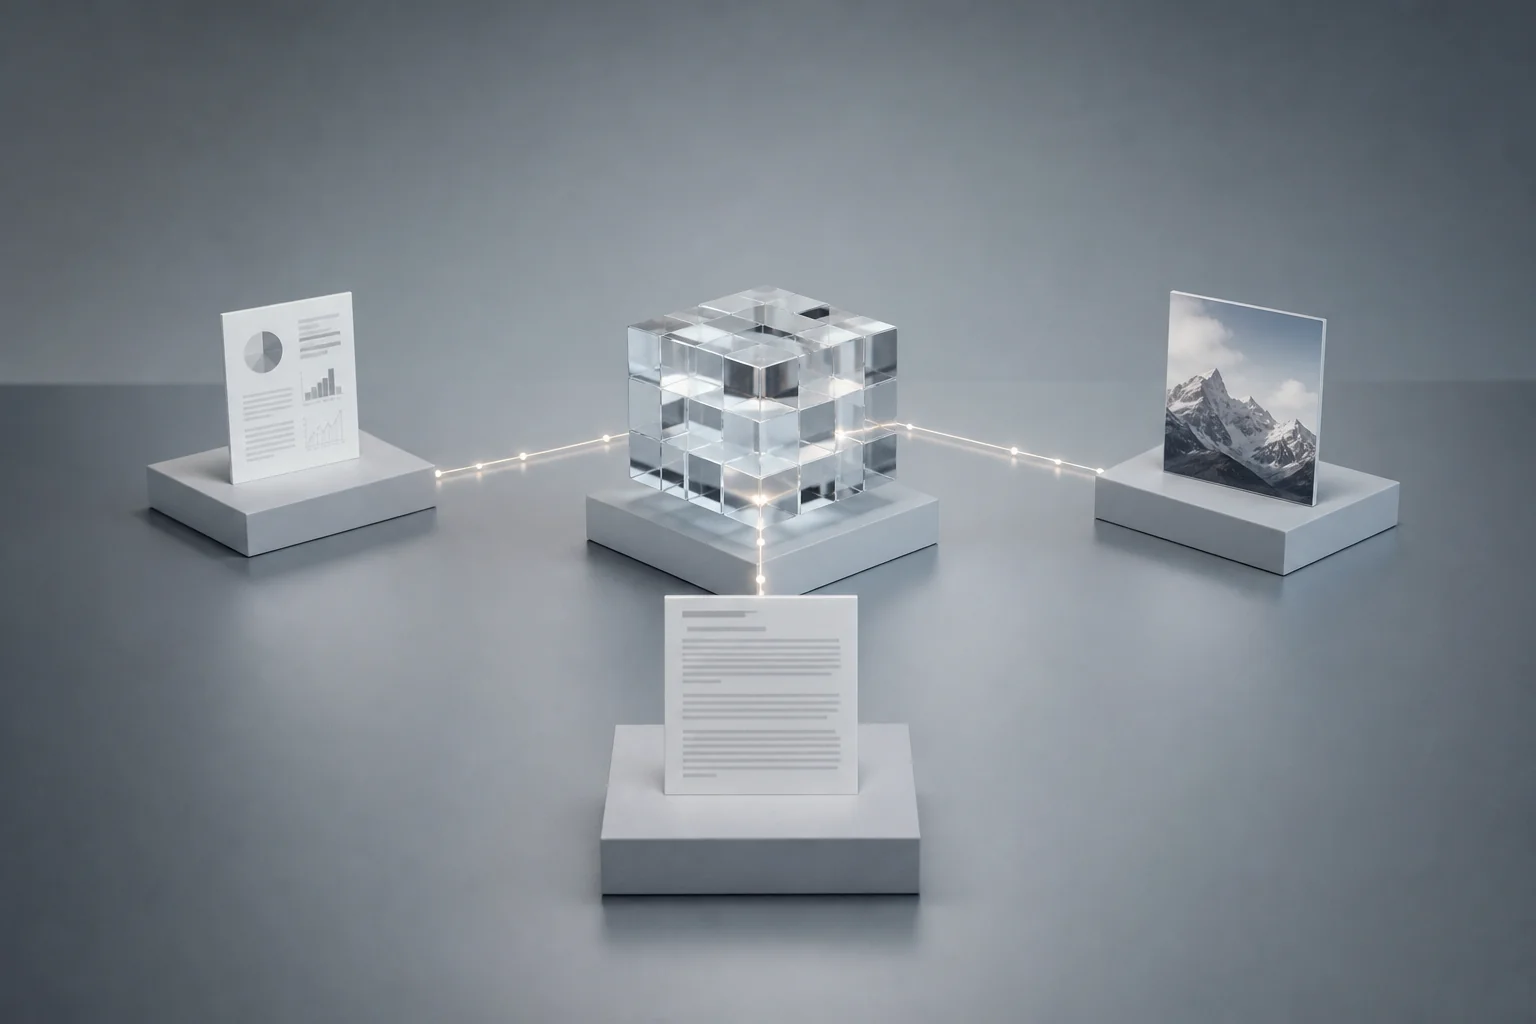
Multimodal embeddings represent a fundamental shift in information retrieval by mapping heterogeneous data types—including text, images, and documents—into a unified, high-dimensional numerical space. On October 9, 2026, industry standards for these systems evolve through the implementation of complex, multi-stage retrieval pipelines that prioritize precision over simple similarity matching.
At the core of this architecture lies the transformation of raw data into vectors, where semantic proximity dictates placement within a shared coordinate system. Unlike traditional unimodal systems that compare like-with-like, multimodal models enable direct cross-format queries by aligning disparate data streams during the training phase. This alignment allows a text-based query to successfully retrieve a relevant image, or vice versa, without the need for explicit manual tagging or metadata.
The foundational methodology for this alignment is contrastive learning, exemplified by OpenAI’s CLIP model, which utilizes dual encoders to process image-text pairs. By training these encoders simultaneously on massive datasets—approximately 400 million pairs in the case of CLIP—the system learns to minimize the distance between matching items in vector space while maximizing the distance between unrelated pairs. This mathematical approach ensures that the model captures the underlying relationship between a visual concept and its textual description.
Newer iterations, such as Google’s Gemini Embedding 2, expand this capability to include video, audio, and structured documents within a single, unified model architecture. These systems leverage larger parameter counts to handle the increased complexity of multi-format data, allowing for more nuanced retrieval across diverse enterprise archives. The ability to process these varied formats simultaneously marks a significant departure from earlier, more constrained embedding techniques.
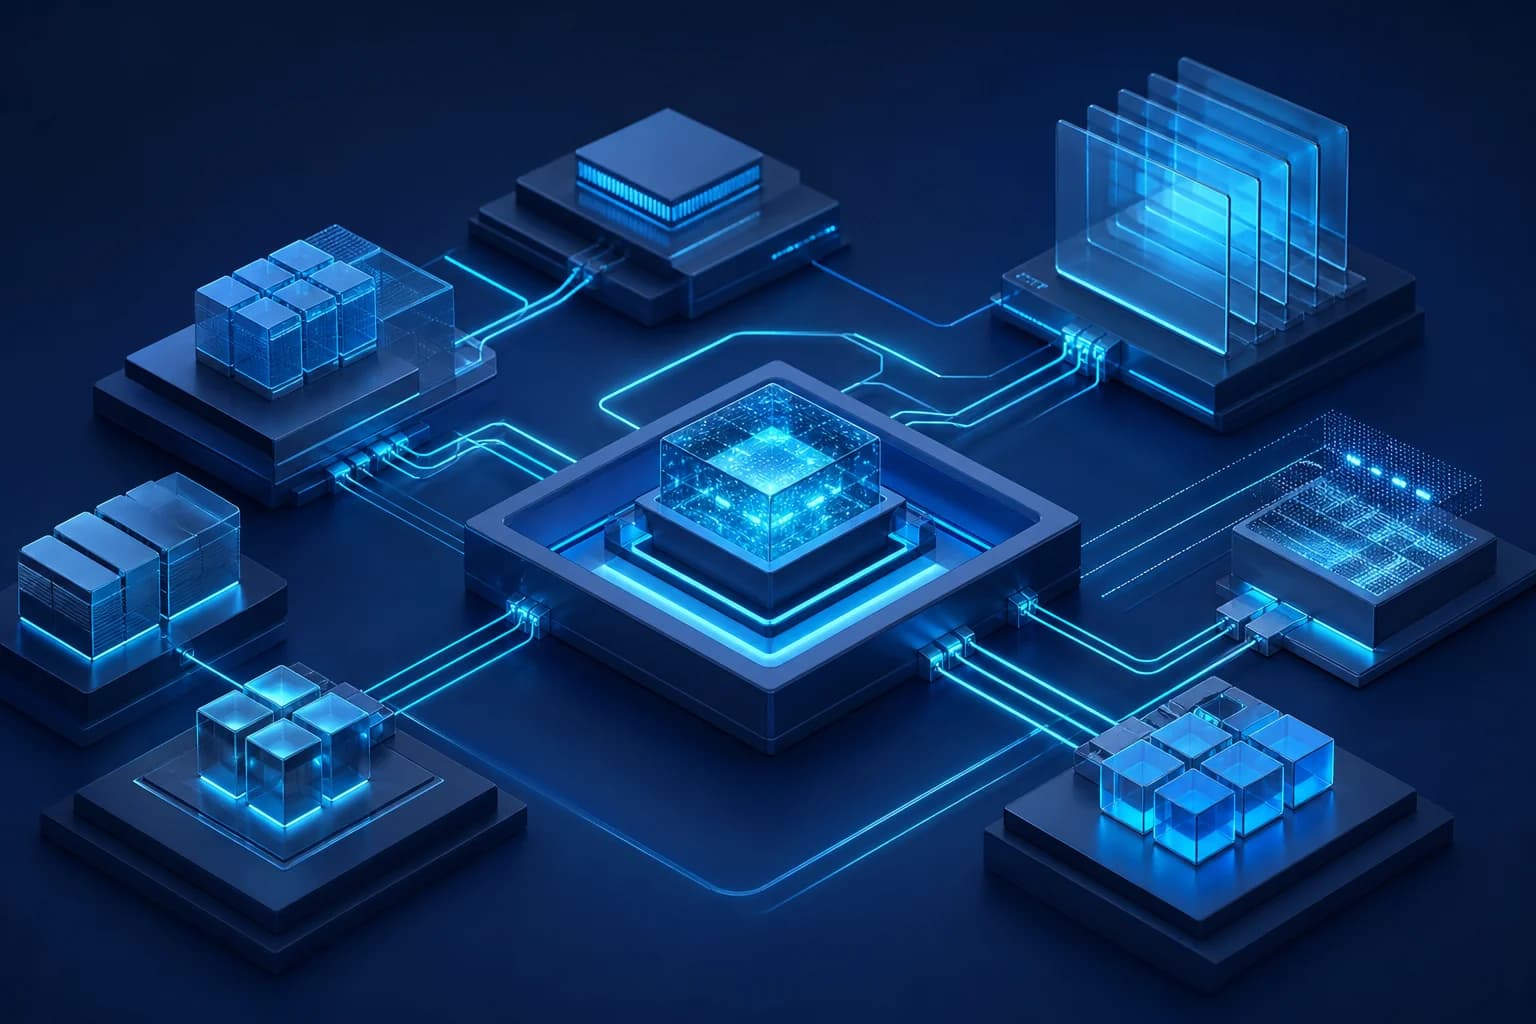
Vector database selection and index design remain critical variables in system performance, with common implementations including Pinecone, Milvus, and Weaviate. These databases often employ approximate nearest-neighbor algorithms, such as hierarchical navigable small-world graphs, to facilitate high-speed retrieval across massive datasets. The efficacy of these searches is not merely a function of database size but is deeply dependent on the chosen embedding dimension, hardware configuration, and the specific model architecture employed.
Teams should benchmark several vector configurations before full-scale deployment to balance search latency against retrieval accuracy. Smaller vectors can reduce storage costs and improve query speed, but they may sacrifice the granularity required for highly specific domain tasks. Rigorous testing of these parameters ensures that the chosen database architecture aligns with the specific performance requirements of the application.
Enterprises must distinguish between the retrieval of a candidate result and the verification of its accuracy, as similarity does not equate to truth. A system might correctly identify a visually similar machine part, yet fail to distinguish between specific revisions or compliance-critical specifications. Consequently, high-stakes environments in legal, scientific, or procurement sectors require a dedicated verification layer to validate retrieved data before it enters a decision-making workflow.
Model compatibility poses a significant challenge for long-term maintenance, as embeddings generated by different models or versions often occupy fundamentally different representation spaces. Mixing incompatible vectors within a single similarity search index leads to degraded retrieval quality and unpredictable results. Engineering teams must prioritize rigorous validation when upgrading models, often necessitating a complete re-embedding and re-indexing of existing data assets to maintain system integrity.
The integration of multimodal embeddings into retrieval-augmented generation pipelines further complicates the governance framework. While these models allow for the inclusion of visual evidence alongside text, they also introduce risks regarding data exposure and unauthorized access. A successful semantic match does not inherently respect existing enterprise permissions, meaning that access controls must be enforced at the retrieval layer to ensure that sensitive documents or images remain restricted to authorized users.
The transition from experimental search implementations to production-grade enterprise systems shifts the burden from model development to operational governance. Organizations that succeed in this domain will be those that treat verification, model lifecycle management, and access control as first-class citizens in their data architecture. The ability to query previously siloed archives—such as scanned diagrams and audio recordings—offers a substantial competitive advantage, provided the underlying retrieval mechanisms are both accurate and secure.